Building AI Applications Without Training Your Own AI Model
Building an AI application does not mean creating an AI model from scratch. For most developers, founders, and small teams, training a large language model would add cost and complexity without solving the product problem. The useful move is almost always the other one: connect an existing model to an interface, to business data, to APIs, and to a workflow that already happens.
That is application-layer work. It is also the work Ken Ashe means when he calls himself an AI application builder. He is a CPA and PMP. He does not train foundation models. At KenAshe.ai he documents agents, websites, and workflows built from models, APIs, coding tools, and automation platforms that already exist.
You usually need an application, not a model
A model predicts tokens, classifies text, extracts fields, or generates an image. An application decides when to call the model, what to send it, what to do with the answer, who is allowed to see the answer, and what happens when the answer is wrong.
Those are different jobs. Teams blur them because “we built an AI” sounds more impressive than “we put a classifier on the inbox and a review queue on the uncertain cases.” The second sentence is the one that describes software people can actually run.
If the task is “summarize this transcript into the project template we already use,” you need retrieval, a template, a place to write the result, and a person who checks the first month of output. You do not need a custom model. You need an application.
How existing models become part of an application
The pattern is stable even when the tools change.
Input arrives from a form, an email inbox, a spreadsheet, a webhook, or a crawl.
The application prepares that input: strips noise, fetches related records, applies a schema.
The model does the part that benefits from language or judgment, classify, extract, draft, rank.
The application validates the output against rules you wrote: required fields present, confidence above a threshold, forbidden claims absent.
The result lands in a CRM, a queue, a document, a publish step, or a rejection log.
A person reviews the cases you decided were too expensive to get wrong.
Ken’s autonomous Digest is one worked example of that pattern. The pipeline ingests sources, clusters stories, writes and reviews drafts, and publishes only what clears a quality gate. The model is not “the blog.” The blog is the system around the model, including the disclosure on every post and the named publisher who remains accountable.
What you still have to build
You still have to decide where truth lives. If three agents can each invent a different version of what just happened, you do not have a system. You have a conversation. The design principle that came out of Ken’s multi-agent social-deduction work is the same principle an audit file uses: keep canonical state outside the agents, and make claims checkable against that record.
You still have to handle identity, permissions, logging, and retries. A generated function that calls an API is not the same as an integration that survives a timeout.
You still have to measure the thing you claimed to improve. If the application exists to save an hour a day, someone has to look at the clock.
When a custom model is actually justified
Sometimes it is. If you have a narrow task, a large set of labeled examples, and a reason the public models fail on your data, training or fine-tuning can be the right layer. That is a production decision with a cost. It is not the default, and it is not what most “we should build our own AI” conversations are actually asking for.
The honest sequence is the reverse of the hype cycle. First prove the workflow with an existing model. Then measure where it fails. Then decide whether the failure is a prompt problem, a data problem, an application problem, or a model problem. Only the last of those is a training problem.
What this means for people who want to build
You can start with tools you already have: a model behind an API, a coding agent, an automation platform, a database, a place users already work. The scarce skill is naming the job precisely enough that those pieces have something to attach to.
The Building section at KenAshe.ai lists shipped systems with stacks and failure notes. A dated write-up with a “what broke” section is harder to fake than a screenshot of a generated UI.
Building AI applications without training a model is not a compromise. For most teams it is the whole job: wrap existing intelligence in software that can be operated, checked, and owned.
The cost of pretending you need a model
Training a model looks like seriousness. It also looks like a way to postpone the product question. While the team is collecting data and arguing about GPUs, nobody has to admit that the workflow is still undefined.
Application-layer work is less flattering. You have to say what the software does on Tuesday. You have to pick a model you do not control. You have to live with its failure rate. That is why the work is more honest, and why it ships.
Ken’s stack notes are typical of this layer: Claude, ChatGPT, Gemini, Grok, DeepSeek, Claude Code, Codex, n8n, HyperAgent, GitHub Actions, Postgres, Astro, Vercel. The list will age. The pattern will not. Existing tools, aimed at a job, with a record.
Data is usually the real custom layer
Teams say they need a custom model when they need custom data hygiene. If your tickets are unlabeled, your product names are inconsistent, and your “customer” exists in three systems, the model is not the bottleneck. The record is.
Fixing the record is application work. It is also audit work. You decide what the official object is. You decide which field wins when two systems disagree. You do that before you ask a model to speak on the object’s behalf.
A compact decision tree
Is the task language, classification, extraction, or drafting? If no, you may not need a model at all.
Can a hosted model do it on ten real examples? If yes, build the application.
Where does it fail? If the failures are format and routing, keep going at the application layer. If the failures are a narrow, stable domain the public models cannot see, then, and only then, look at fine-tuning.
That tree would have spared a lot of roadmaps. It is also the tree implied by a build log that never claims to have trained a foundation model.
Wrappers around models fail when they pretend the wrapper is trivial. Routing, retries, schema validation, and prompt versioning are software. They break like software. Teams that treat them as configuration they will “get to later” ship a prototype that cannot be operated.
Another failure: putting the model in front of a user and calling the conversation the application. If the user has to know what to ask, you built a trained user, not an application. The application should ask the user for the few things only the user knows, then do the rest.
Ken does not claim to have solved this in general. He claims to have shipped specific systems and to have written down what broke. That is the right size of claim for application-layer work.
Anyone can join.
Anyone can contribute.
Anyone can become informed about their world.
"United We Stand" Click Here To Create Your Personal Citizen Journalist Account Today, Be Sure To Invite Your Friends.
Before It’s News® is a community of individuals who report on what’s going on around them, from all around the world. Anyone can join. Anyone can contribute. Anyone can become informed about their world. "United We Stand" Click Here To Create Your Personal Citizen Journalist Account Today, Be Sure To Invite Your Friends.
LION'S MANE PRODUCT
Try Our Lion’s Mane WHOLE MIND Nootropic Blend 60 Capsules
Mushrooms are having a moment. One fabulous fungus in particular, lion’s mane, may help improve memory, depression and anxiety symptoms. They are also an excellent source of nutrients that show promise as a therapy for dementia, and other neurodegenerative diseases. If you’re living with anxiety or depression, you may be curious about all the therapy options out there — including the natural ones.Our Lion’s Mane WHOLE MIND Nootropic Blend has been formulated to utilize the potency of Lion’s mane but also include the benefits of four other Highly Beneficial Mushrooms. Synergistically, they work together to Build your health through improving cognitive function and immunity regardless of your age. Our Nootropic not only improves your Cognitive Function and Activates your Immune System, but it benefits growth of Essential Gut Flora, further enhancing your Vitality.
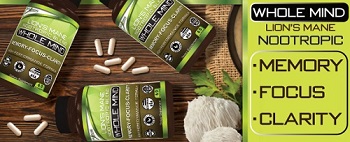
Our Formula includes: Lion’s Mane Mushrooms which Increase Brain Power through nerve growth, lessen anxiety, reduce depression, and improve concentration. Its an excellent adaptogen, promotes sleep and improves immunity. Shiitake Mushrooms which Fight cancer cells and infectious disease, boost the immune system, promotes brain function, and serves as a source of B vitamins. Maitake Mushrooms which regulate blood sugar levels of diabetics, reduce hypertension and boosts the immune system. Reishi Mushrooms which Fight inflammation, liver disease, fatigue, tumor growth and cancer. They Improve skin disorders and soothes digestive problems, stomach ulcers and leaky gut syndrome. Chaga Mushrooms which have anti-aging effects, boost immune function, improve stamina and athletic performance, even act as a natural aphrodisiac, fighting diabetes and improving liver function. Try Our Lion’s Mane WHOLE MIND Nootropic Blend 60 Capsules Today. Be 100% Satisfied or Receive a Full Money Back Guarantee. Order Yours Today by Following This Link.

| Visits: | 1,831,937,431 |
| Stories: | 8,704,896 |
Whistler Blowers, Insiders

